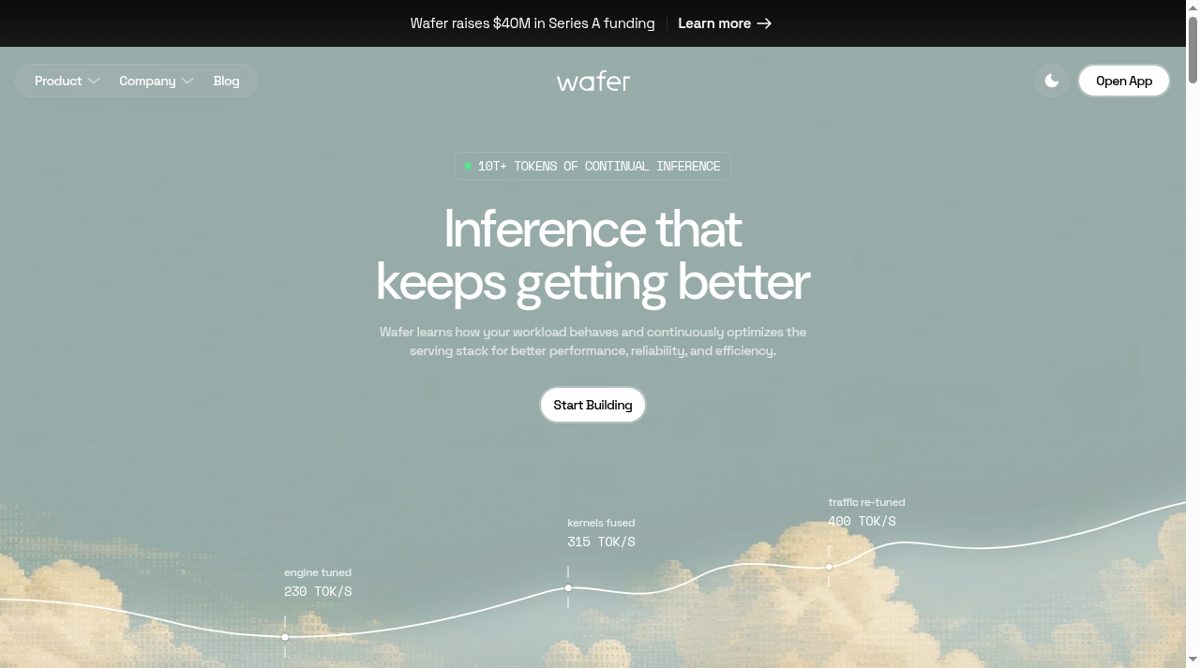
Wafer provides AI inference infrastructure built around the idea that a serving configuration should keep adapting after deployment. Its dedicated offering starts with a model, the shape of application traffic and service-level targets, then tunes the endpoint around those requirements. The company describes optimizing batching, caching, routing and decoding against real request patterns rather than choosing a setup from a generic benchmark alone.
The broader optimization process spans model choices, serving engines, kernels and hardware. Wafer profiles bottlenecks, measures candidate configurations and continues checking the deployed workload as traffic and models change. The site says candidate changes must preserve correctness and meet reliability targets before shipping. Performance figures and customer results shown on the website are workload-specific, not a speed guarantee for an unrelated application. Teams evaluating Wafer need to establish supported models, deployment conditions and commercial terms for their own endpoint. It is intended for developers operating model-backed products who want inference behavior tuned across the stack instead of managing each performance setting in isolation.