ChatLLaMA
A ChatGPT style chatbot for Facebook's LLaMA
About ChatLLaMA
ChatLLaMA — A ChatGPT style chatbot for Facebook's LLaMA. It was shared on Show HN in 2023 and received 402 upvotes on Hacker News. Serve and scale open-source and custom AI models on the fastest, most reliable inference platform. Inference Platform: Deploy AI models in production | Baseten Use your OpenAI commitments on Baseten open models . Start deploying Learn more Pre-optimized Model APIs Test new workloads, prototype products, or evaluate the latest AI models optimized to be the fastest in production — instantly. Baseten delivers the infrastructure, tooling, and expertise needed to bring the most performant AI products to market—fast. Learn More Learn More DevEx built for rapid iteration Deploy, optimize, and manage your models and compound AI with a delightful developer experience built into Baseten's inference platform. We offer single-tenant and self-hosted deployments for extra security. Learn more Engineered for the most demanding Gen AI apps Custom performance optimizations tailored for Gen AI applications are baked into the Baseten Inference Stack. Rapid image generation Serve custom models or ComfyUI workflows, fine-tune for your use case, and quickly generate high-quality images on our inference platform. SOTA text-to-speech We built real-time audio streaming to power AI phone calls, voice agents, translation, and more with the lowest time to first byte (TTFB). The fastest embeddings Baseten Embeddings Inference (BEI) has over 2x higher throughput and 10% lower latency than any other solution on the market. We really appreciate the level of commitment and support from your entire team. Doctors rely on speed when treating patients, and that improvement has been critical to our product experience. Jagath Jai Kumar Full Stack Engineer, OpenEvidence With the launch of Brain MAX we've discovered how addictive speech-to-text is - we use it every day and want it everywhere. Introducing it on Hacker News, the author wrote: "ChatLLaMA is an experimental chatbot interface for interacting with variants of Facebook's LLaMA. Currently, we support the 7 billion parameter variant that was fine-tuned on the Alpaca dataset. Not trying to shill anything; just want to build and share cool stuff."
Community AMA
Ask the founder anything!
No questions yet. Be the first to ask!
Community Perks
Check back soon for exclusive offers
We're cooking up something special with 'ChatLLaMA' to bring you exclusive perks!
The kitchen is busy - amazing deals are coming soon! 🔥
You Might Also Like...
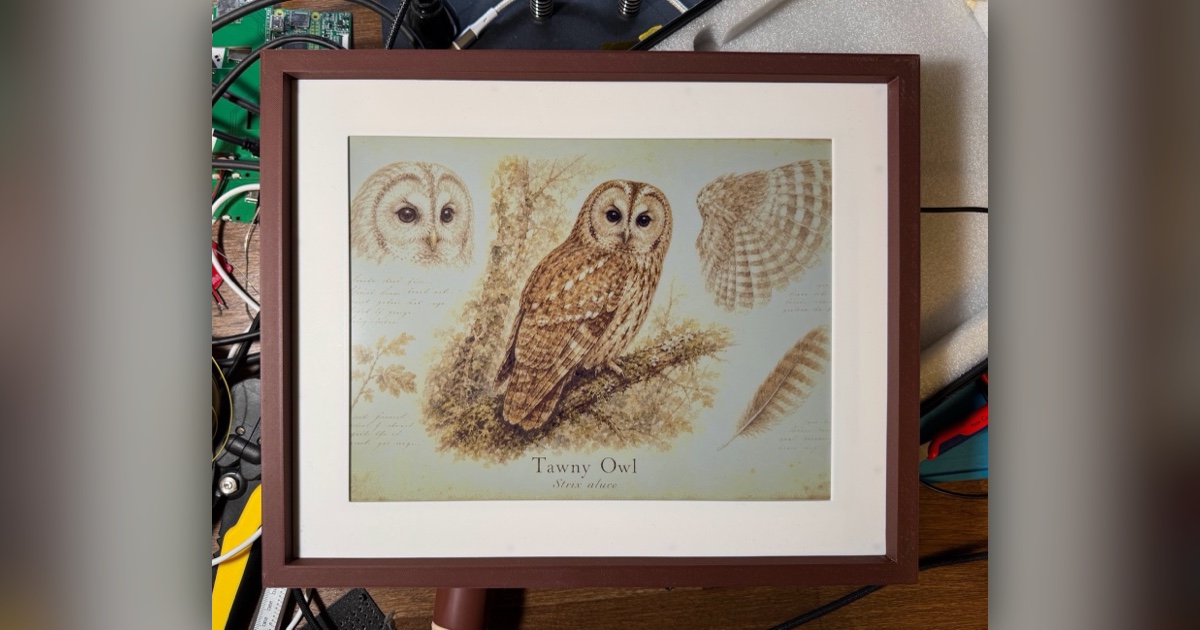
FrameOSoperating system for single function smart frames
AutomatischOpen source workflow automation, an alternative to Zapier
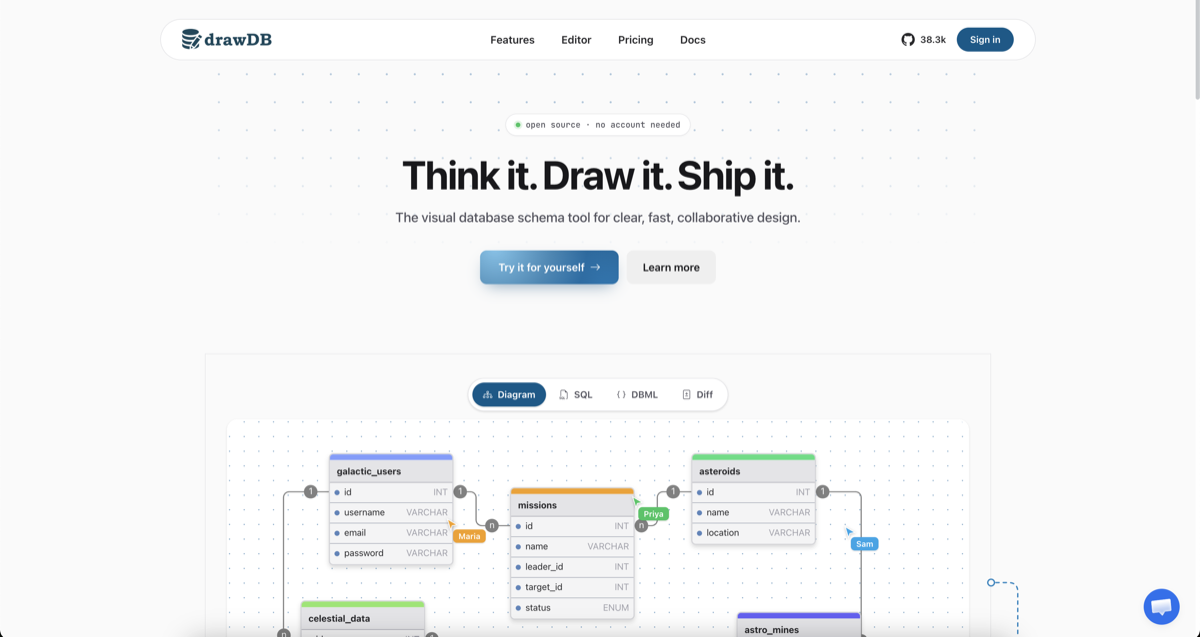
DrawDBopen-source online database diagram editor (a retro)
MemoriesFOSS Google Photos alternative built for high performance
Alternatives to ChatLLaMA: FrameOS, Automatisch, DrawDB, Memories · Compare all alternatives ›